
WordPress PHP Worker Saturation: Symptoms, Evidence and Capacity Decisions
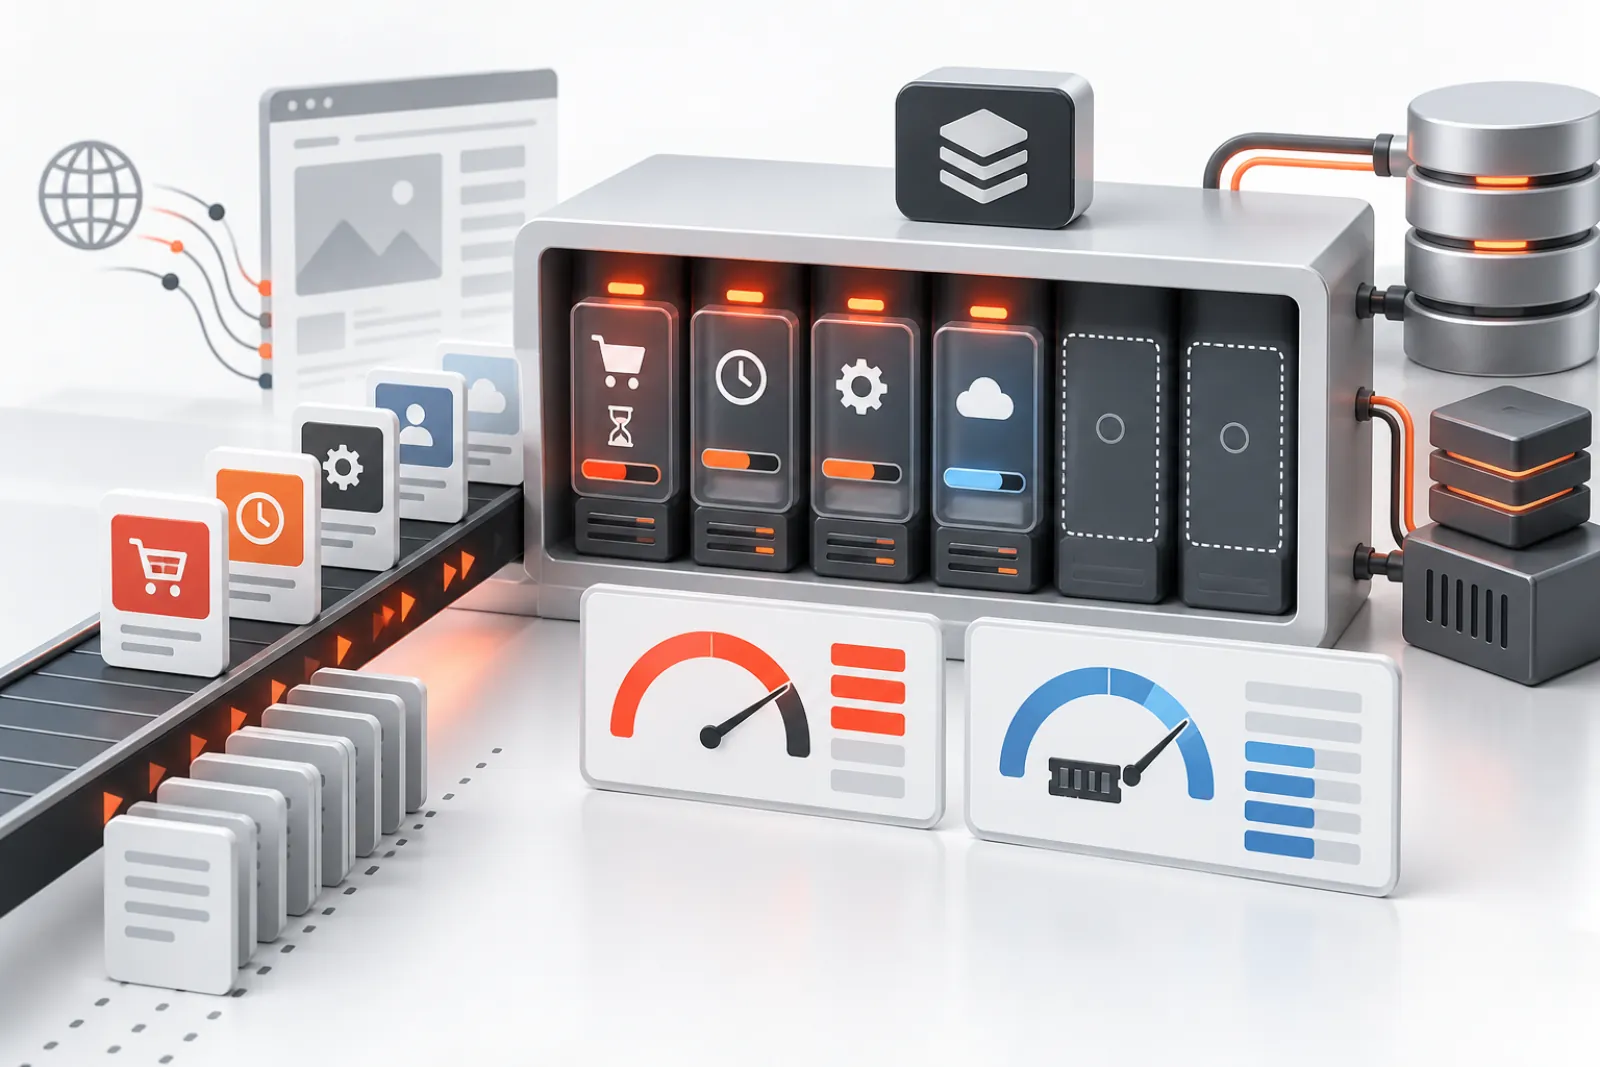
PHP worker saturation happens when all available workers are busy and new WordPress requests must queue. The queued request may execute quickly once a worker starts, so application timing alone can miss the delay. You need hosting queue evidence and in-request evidence from the same timestamps.
Understand the capacity model
A worker handles one PHP request at a time. Cached pages may bypass PHP, while checkout, wp-admin, REST, AJAX, cron and logged-in pages require it. Throughput depends on worker count and how long each request occupies a slot. Doubling workers can increase database and memory pressure if long requests remain unfixed.
| Signal | Interpretation |
|---|---|
| High queue time, normal in-app runtime | Worker shortage or upstream queue |
| All workers busy with remote waits | Latency problem, not CPU capacity |
| Memory near host limit | Adding workers risks kills or swapping |
| Database connections saturated | More PHP concurrency can worsen throughput |
| Short spikes during cron batches | Scheduling and workload isolation opportunity |
Collect matching evidence
- Record p50, p95 and p99 user response time.
- Obtain worker busy/idle counts and queue length.
- Capture request start, PHP start and completion when the platform exposes them.
- Group active requests by path and duration.
- Match WordPress snapshots for database, hooks, HTTP, memory and errors.
- Check database connections, CPU, RAM and disk I/O.
Reduce worker occupancy first
Fix the longest common requests: remote timeouts, unbounded queries, synchronous webhooks, oversized reports and cron jobs. Cache safe public output, batch background work, and remove duplicate polling. A 100 ms improvement across a high-volume endpoint can free more capacity than optimizing one rare ten-second request.
Then evaluate worker count
Estimate peak resident memory per representative request, multiply by candidate workers and preserve headroom for the operating system, database, Redis, opcode cache and maintenance jobs. Load-test with realistic route mix. Stop adding workers when database latency, errors or context switching worsen.
Worked example
Eight workers serve a store. During an import, four run 40-second batches and three wait on a tax API; only one remains for checkout and wp-admin. CPU is moderate, yet users wait. Moving the import to bounded background batches and fixing the API cache releases slots. Increasing workers without those changes would increase memory and database concurrency while leaving long occupancy intact.
Protect critical traffic
Stagger cron, limit import concurrency and separate workloads where the host permits. Apply rate limits to abusive endpoints. Do not blindly prioritize wp-admin over payment callbacks or webhooks; define which routes protect revenue and integrity.
Calculate a safe starting range
If a representative heavy request uses 120 MB at peak, ten simultaneous workers could require roughly 1.2 GB before accounting for the operating system, database, cache and variation. Do not treat that multiplication as an exact formula; shared memory and workload mix matter. Use it to reject obviously unsafe settings, then validate with load tests and observed resident memory.
Find queueing before PHP
Compare reverse-proxy or web-server request time with the application’s measured runtime. The difference may include connection handling and waiting for a PHP slot. PHP-FPM status, hosting analytics or APM can expose active, idle, max-active and queued requests. Without this boundary, a 200 ms application snapshot can coexist with a five-second browser wait.
Model the route mix
A test containing only cached homepages tells you nothing about workers. Include checkout, login, REST, AJAX, wp-admin, uncached search and background callbacks in realistic proportions. Add an upstream slowdown and database latency scenario. The system should degrade predictably without starving critical routes.
Scale vertically or horizontally?
More memory and CPU on one node can support additional workers, while more web nodes can spread request execution. Horizontal scaling also requires shared sessions, cache, uploads and database capacity. Neither fixes a ten-second blocking call. Reduce occupancy first, then choose architecture from measured demand and operational complexity.
Turn evidence into a capacity decision
A full worker pool can coexist with idle CPU when requests wait on a database lock, remote API, filesystem or session lock. First shorten pathological requests, move deferrable work out of the request path and cache safe results. Then load-test production-like traffic and increase workers only within memory and database limits. Scaling one layer without resolving the wait can multiply connections and worsen the outage.
Apply queueing math without pretending it is exact
A worker’s throughput is roughly the inverse of how long it remains occupied. Eight workers handling one-second dynamic requests can complete far fewer requests per second than the same pool handling 100-millisecond work. As utilization approaches the pool limit, small bursts create rapidly growing waits.
Use this relationship to reason about headroom, then validate with the real route mix. Requests vary, caches miss, background jobs arrive in batches and downstream services slow. A simple average cannot predict tail latency, but it can reveal an obviously undersized or over-occupied pool.
Measure the boundary before PHP starts
Collect reverse-proxy arrival time, FastCGI dispatch or queue time, PHP start and response completion where the platform exposes them. PHP application monitoring begins after a worker is assigned, so it may report 200 milliseconds while the browser waited five seconds.
Ask hosting for PHP-FPM status or equivalent: active, idle, total, max active, listen queue, maximum queue and max-children reached. Normalize timestamps and correlate with WordPress snapshots. Without both layers, saturation remains a guess.
| Pattern | Meaning | Response |
|---|---|---|
| Queue grows, all workers active | Pool is saturated | Identify long/common occupants, then test capacity |
| Queue grows, workers below limit | Dispatch, configuration or upstream issue | Inspect web server and process manager |
| Workers active, CPU low | Waiting on I/O, database, locks or remote calls | Trace waits before adding CPU |
| Memory kills rise at peak | Pool exceeds safe resident memory | Reduce request memory or workers |
| Database latency rises with workers | Downstream saturation | Optimize and cap concurrency |
Build a route occupancy profile
Group dynamic requests by path class, volume, median, p95, peak memory, database time, remote wait and cache status. Multiply volume by occupied seconds to rank total worker demand. A moderately slow high-volume endpoint often matters more than one rare extreme request.
Include admin AJAX, REST, checkout, login, search, webhooks, cron loopbacks and queue workers. Full-page cache hits may never enter PHP and should not dilute the dynamic profile. Redact query strings and customer identifiers.
Identify waits that consume slots
External APIs, database locks, slow filesystem access, PHP session locks and object-cache timeouts can occupy a worker without continuous CPU. Trace the longest common requests. Use strict timeouts, optimized queries, correct cache behavior and asynchronous queues where the business allows.
Do not simply extend execution time. A larger timeout lets each bad request hold a slot longer. Increase it only for bounded legitimate work after deciding how interactive traffic remains protected.
Separate background work from interactive demand
Limit imports, exports, backups, image processing and reports so they cannot claim every worker. Stagger schedules and process bounded batches. Where hosting supports separate pools or workers, isolate long background jobs while preserving database and memory limits.
Reserve capacity based on business priorities: checkout, payment callbacks, login, publishing and critical webhooks. The exact order depends on the site. Rate-limit abusive routes and prevent cron overlap before buying capacity.
Calculate a memory-safe pool
Measure resident memory and PHP peak memory for representative light, normal and heavy requests. Multiply a conservative mix by candidate workers, then leave room for the operating system, web server, database, Redis, opcode cache and maintenance. Consider that image jobs or imports may briefly exceed ordinary peaks.
A PHP memory_limit is a ceiling per process, not a reservation, and resident memory may differ. Use observed process metrics under load. Adding workers until the host swaps or kills processes lowers reliability.
Protect the database and cache from added concurrency
More PHP workers can create more database connections, queries and simultaneous cache requests. Load-test connection limits, lock waits, query latency, Redis latency and external provider limits. Throughput can fall after a point because downstream contention dominates.
Increase in small steps with rollback thresholds. If queue time falls but database p95 and errors rise, the system has moved the bottleneck rather than solved it.
Worked case: slow license service saturates wp-admin
A managed site has twelve workers. A license endpoint times out after ten seconds on every admin page, and editors refresh repeatedly. CPU stays moderate, but all workers wait remotely and public uncached requests queue.
The plugin scopes and caches the check, uses a short timeout and refreshes status asynchronously. Worker occupancy falls without changing pool size. A later load test shows the existing capacity is adequate. Adding workers first would have multiplied simultaneous calls to the failing provider.
Worked case: more workers overload the database
A store increases workers from eight to twenty-four after peak queues. Queue time initially falls, then checkout errors rise as database connections and lock waits increase. Heavy search requests issue repeated unindexed queries.
The team restores the prior safe pool, fixes the query, caches eligible search results and retests. It then increases to twelve workers within measured memory and database headroom. Capacity change becomes the final step, not the first guess.
Plan horizontal scaling carefully
Multiple web nodes can spread PHP execution, but sessions, uploads, object cache, cron ownership and database remain shared concerns. Ensure sticky sessions are not masking PHP session design, offload media consistently, use environment-safe cache prefixes and prevent every node from running the same background job.
Health checks should remove an unhealthy node without sending all traffic to an undersized survivor. Test deployment and failover with realistic dynamic traffic. Horizontal scale adds operations; use it when measured demand and availability justify that complexity.
Respond to active saturation
- Confirm queue and max-worker evidence.
- Group active and recent long requests by route and wait.
- Pause or limit the proven background or abusive source.
- Apply a narrow timeout, cache or rate limit where safe.
- Protect checkout, login, payment and integrity routes.
- Restore service, then reproduce the dominant occupancy on staging.
- Optimize and load-test before making permanent pool changes.
Preserve process and request evidence before restarting PHP. A restart can clear the queue while hiding the owner.
Set capacity alerts and forecasts
Track busy percentage, queue depth and age, max-children events, request occupancy by route, memory, kills, database connections and cache latency. Alert on sustained conditions before all workers are occupied. Annotate campaigns, imports and releases.
Forecast from traffic growth and occupied seconds per transaction. Revisit after product, plugin, PHP or infrastructure changes. Capacity is a living model, not a one-time worker number copied from another site.
Verification plan
Replay a production-like mix with cached and uncached public pages, login, checkout, REST, AJAX, wp-admin and background work. Include a slow upstream and cache loss. Compare queue p95, user response, throughput, errors, memory, database and cache health.
Observe production through the original peak window. Confirm background jobs still complete and no critical route is starved. Keep the previous pool configuration and workload limits available for rollback.
Understand process-manager configuration
PHP-FPM can start workers statically, dynamically or on demand depending on host configuration. Relevant controls include maximum children, start and spare servers, request limits, idle timeouts and slow logging. Managed hosting may abstract them, but support can still provide pool evidence.
Do not copy values from another server. Hardware, extensions, plugins, traffic mix and database topology differ. Change one capacity variable at a time and retain the prior configuration.
Use slow logs and stack samples safely
A process-manager slow log or application profiler can show where long requests spend time after execution begins. Enable it with a threshold and short diagnostic window appropriate to production risk. Correlate process ID, path and timestamp with access and WordPress evidence.
Stacks can expose filenames, plugins and query context. Restrict access and redact support exports. Disable temporary high-overhead profiling after the investigation or convert only low-cost metrics into monitoring.
Prevent a thundering herd after recovery
When PHP restarts, caches flush or an upstream returns, many queued requests and jobs may begin together. Rate-limit backlog release, warm safe caches, stagger background workers and keep provider concurrency within contract. Recovery can create a second outage if every retry fires immediately.
Test cold start with realistic traffic. Watch database queries, Redis, external calls and memory. A steady-state load test does not prove safe recovery.
Protect sessions and long-held locks
PHP session locking or plugin locks can serialize requests for one user, making an editor or checkout appear worker-starved even when the pool has idle capacity. Inspect whether concurrent AJAX requests wait on the same session. Close sessions as soon as writes finish where the application design permits.
Database, filesystem and cache locks need owners and expiry. A stuck lock can occupy workers until timeout. Fix the shared critical section rather than increasing pool size.
Worked case: admin AJAX polling fills the pool
A dashboard opens six polling requests every five seconds. Each waits two seconds on a report lock. Ten administrators can occupy the pool although public traffic is low. Metrics show repeated admin-ajax.php actions.
The plugin consolidates polling, caches report status and reduces frequency when the tab is hidden. It releases the lock before rendering. Worker occupancy falls, and functional tests confirm live status remains timely.
Worked case: image jobs exceed memory headroom
A site increases workers for traffic, then a bulk media import starts. Several workers decode large images simultaneously and the host kills processes. More concurrency reduced memory available per job.
The team caps image-job concurrency, validates dimensions, processes bounded batches and restores a memory-safe worker limit. Imports move away from peak traffic. Completion is slower, but checkout remains stable and no workers die.
Prepare a hosting escalation package
Provide timestamps, domain, proxy response time, application runtime, worker busy/idle and queue metrics, active path groups, resident memory, CPU, database connections, cache latency and recent changes. Ask for pool limits and max-children evidence.
State the predicted remediation: shorten endpoint X, limit job Y or test workers from N to M within memory. Hosting can act on a bounded request more effectively than “increase PHP workers.”
Govern permanent capacity changes
Record the baseline, tested route mix, memory model, downstream limits, old and new pool settings, predicted throughput, load-test result, rollback and owner. Review after traffic or plugin changes. Remove emergency settings that lack evidence.
Capacity is successful when queue and user latency improve without raising errors, memory kills, database contention or unfinished background work. Keep all guardrails in the dashboard.
Distinguish origin saturation from CDN behavior
A full-page cache or CDN can hide origin distress for anonymous pages while authenticated users, checkout and APIs queue. Compare cache-hit and cache-miss headers and test an uncached health route designed for operations. Do not purge the entire cache during a peak merely to test origin; that can send a thundering herd into the saturated pool.
Warm critical cacheable pages after a planned restart and monitor origin request rate. Keep checkout and personalized responses correctly uncached even when capacity is tight.
Use admission control for expensive work
Limit concurrent imports, exports, scans and report generation. Reject or queue additional requests with a clear status rather than letting all of them occupy workers and fail. For public abuse, rate-limit by route and risk-aware source groups without blocking legitimate payments or webhooks.
Admission controls need observability: accepted, queued, rejected, completed and oldest age. A hidden backlog can preserve web latency while violating business completion requirements.
Review PHP memory and timeout together
A higher memory limit can let heavy requests live longer and allow fewer safe workers within host RAM. A longer execution timeout increases maximum occupancy. Change either only after measuring the request and deciding whether the workload belongs in an interactive process.
For legitimate heavy work, use bounded background batches with checkpoints. For unbounded or leaking work, fix the owner. Limits are safety controls, not performance tuning knobs.
Definition of done
- Queue time before PHP is measured and correlated with the same incident window.
- Dominant routes and waits are ranked by total occupied seconds.
- Background concurrency and abusive traffic cannot claim the full pool.
- Worker count fits observed memory and downstream connection limits.
- Cold-start, upstream-failure and peak route-mix tests pass.
- Checkout, login, administration and required jobs meet their service objectives.
- Configuration, rollback, monitoring and capacity owner are documented.
Review capacity after application releases
Plugin and theme releases can change request memory, query volume, remote dependencies and cacheability. Re-run the reference route mix after major changes and compare occupied seconds, not only page-load scores. A small regression multiplied by high traffic can consume the pool’s safety margin.
Track data growth as well. Orders, users, products and revisions can turn a previously bounded query into a long worker occupant. Forecast and remediate before max-children events become routine.
Keep a capacity decision record
Store the pool scope, host resources, route mix, test tool, concurrency, observed memory, queue distribution, downstream limits, chosen setting and approval. Include rejected settings and why they failed. This prevents later operators from restoring an unsafe “higher” worker count.
Review the record during hosting migrations and PHP upgrades. A new runtime or node invalidates old memory and throughput assumptions; measure again.
Retain one sanitized saturation trace and one healthy comparison. They let future responders identify the queue boundary and dominant route quickly without repeating unsafe experiments during peak traffic.
Test maintenance and recovery events as part of capacity planning. Cache flushes, deploy restarts, database failover and queue replay can temporarily multiply origin work. Reserve enough headroom for a controlled recovery, and document which background jobs should remain paused until interactive traffic is stable.
How WPStack TOP Load Monitor helps
WPStack TOP Load Monitor provides request snapshots for runtime, memory, query cost, duplicates, errors and request context. It helps explain what occupied a worker after PHP started. Worker queue length and process-pool limits must come from the host or PHP-FPM layer.
Acceptance criteria
- Queue time and p95 response improve under the same load.
- No rise in database saturation, timeouts or memory kills.
- Checkout, login and admin remain responsive during background work.
- Cron and queues still complete within business requirements.
- The chosen worker limit has documented memory headroom.
Related WPStack guides
Frequently asked questions
Is worker saturation the same as high CPU?
No. Workers can be busy waiting on databases or remote services while CPU remains moderate.
Will more workers always help?
No. They consume memory and increase downstream concurrency.
Why is WordPress timing fast while the browser waits?
The request may have queued before PHP began measuring it.
Does Redis add workers?
No. It may shorten some work, which can free existing workers sooner.
References

Aditya Bhimrajka is a technology entrepreneur, product strategist, and software solutions expert with over a decade of experience building scalable web and mobile applications. His expertise spans SaaS, AI, cloud technologies, custom software development, and digital transformation. Passionate about solving real-world business challenges through technology, Aditya shares practical insights on WordPress, plugins, software development, startup growth, product strategy, and emerging technologies. At WPStack, he writes actionable, experience-driven content that helps developers, businesses, and website owners build secure, high-performing, and future-ready WordPress solutions.