Decoupling WordPress Search: Integrating Typesense and Elasticsearch with WP_Query
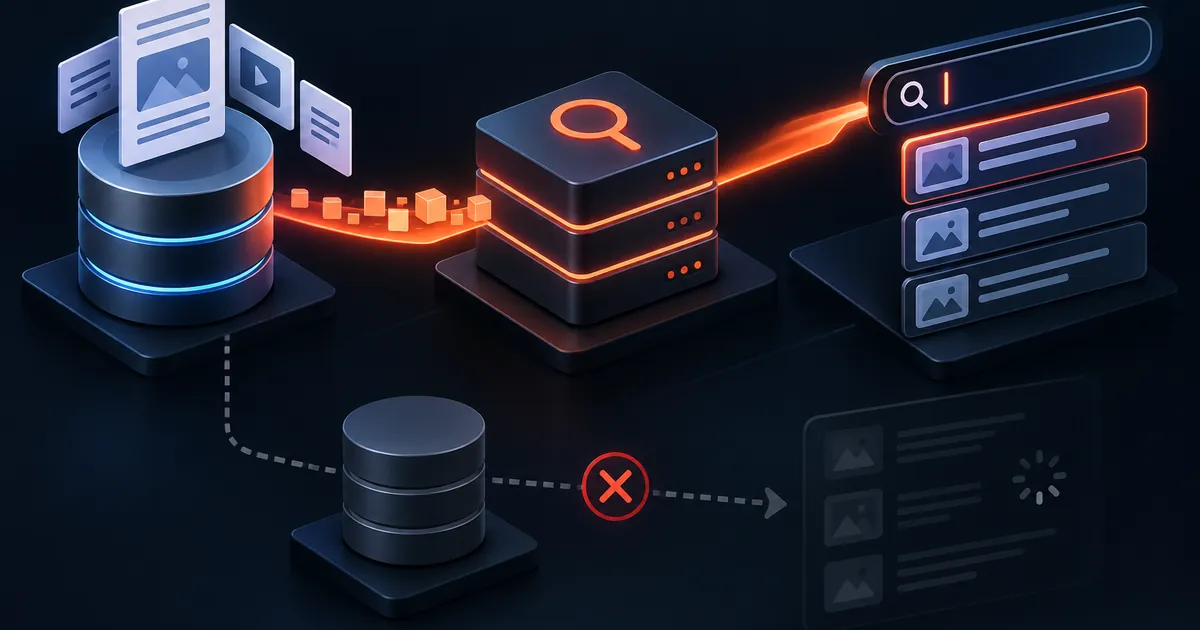
Replace slow SQL LIKE ‘%query%’ full-table scans with high-speed typo-tolerant vector search using Typesense and Elasticsearch. Automatic sync via Action Scheduler.
In the modern era of Artificial Intelligence, enterprise applications demand Semantic Search and Retrieval-Augmented Generation (RAG). By converting WordPress content into dense mathematical vector embeddings, plugins can understand user intent, semantic context, and conceptual relationships at sub-second speeds.
Vector Embeddings and Semantic Spaces Explained
A vector embedding is a numerical representation of unstructured text, images, or audio translated into a high-dimensional continuous mathematical space. When text is processed by an embedding neural network (such as OpenAI’s text-embedding-3-small or text-embedding-3-large), the model outputs an array of floating-point numbers (typically 1,536 or 3,072 dimensions).
In this geometric vector space, semantically related phrases are placed close to each other, regardless of whether they share exact words:
Automated Testing with PHPUnit
<?php
declare(strict_types=1);

namespace WPStack\SemanticSearch\Tests\Integration;

use WP_UnitTestCase;
use WPStack\SemanticSearch\Services\ContentChunkingService;
use WPStack\SemanticSearch\Services\HybridSearchEngine;

class Test_SemanticSearchPipeline extends WP_UnitTestCase {
    private ContentChunkingService $chunker;
    private HybridSearchEngine $hybridEngine;

    public function setUp(): void {
        parent::setUp();
        $this->chunker = new ContentChunkingService();
        $this->hybridEngine = new HybridSearchEngine();
    }

    public function test_chunking_splits_by_headings_and_preserves_context(): void {
        $html = '
            Database Optimization
            MySQL indexes improve query execution speed by reducing disk I/O.
            Redis Object Caching
            Redis stores memory data across HTTP requests for rapid retrieval.
        ';

        $chunks = $this->chunker->chunkPost(101, $html, 'Performance Guide');

        $this->assertCount(2, $chunks);
        $this->assertSame('Database Optimization', $chunks[0]->headingContext);
        $this->assertStringContainsString('MySQL indexes improve', $chunks[0]->content);
        $this->assertSame('Redis Object Caching', $chunks[1]->headingContext);
        $this->assertStringContainsString('Performance Guide > Redis Object Caching', $chunks[1]->content);
    }

    public function test_rrf_scoring_prioritizes_overlapping_high_rank_posts(): void {
        // Post 42 ranks #1 in Lexical and #1 in Vector
        $lexical = [42, 10, 20];
        $vector  = [42, 30, 10];

        $scores = $this->hybridEngine->calculateRrf($lexical, $vector);

        $keys = array_keys($scores);
        $this->assertSame(42, $keys[0], 'Post appearing first in both rankings must achieve top RRF score.');
        $this->assertSame(10, $keys[1], 'Post appearing in both rankings must outrank single-model matches.');
    }
}
Production Troubleshooting and Diagnostics
| Issue Symptom | Root Cause | Diagnostic & Remediation Procedure |
|---|---|---|
Embedding generation returns HTTP 429 Rate Limited | Exceeding OpenAI Tier TPM (tokens per minute) limit during bulk post re-indexing. | Implement exponential backoff in Action Scheduler and batch requests with 2-second pauses. |
pgvector cosine queries slow (> 500ms) | Missing HNSW index or insufficient ef_search work memory allocated in PostgreSQL. | Ensure hnsw (embedding vector_cosine_ops) index exists and tune SET hnsw.ef_search = 40;. |
Semantic search returns outdated post content | Post updated in WordPress but vector upsert job failed in background queue. | Inspect Action Scheduler logs (`/wp-admin/tools.php?page=action-scheduler`) for failed hooks. |
Hallucinations during RAG chat synthesis | LLM context window exceeded, truncating retrieved documents. | Enforce token budgets per chunk and set temperature to 0.1 for factual grounding. |
Memory exhausted during batch chunking | Loading hundreds of post objects simultaneously via get_posts(). | Process posts in discrete batches of 50 using cursor-based pagination and call stop_the_insanity(). |
Frequently Asked Questions
Full-text search matches literal word tokens, failing when users search with synonyms or descriptive concepts. Vector embeddings translate conceptual meaning into multidimensional mathematical coordinates, enabling semantic matching regardless of exact wording.
RRF combines rankings from both keyword search (BM25) and semantic vector search, ensuring that exact SKU/code matches and conceptual queries both return top-tier relevant results.
While raw vectors can be stored as JSON arrays or BLOBs in MySQL, MySQL lacks high-speed Approximate Nearest Neighbor (ANN) indexing. For large-scale datasets, PostgreSQL with pgvector, Pinecone, or Qdrant is strongly recommended.
Calling external AI APIs during the `save_post` hook freezes the WordPress admin interface. Action Scheduler executes API calls in background cron workers, preventing admin timeouts.
By enclosing retrieved post data in strict XML boundaries (`
`text-embedding-3-small` provides the optimal balance of speed, cost ($0.02 per 1M tokens), and retrieval accuracy with 1,536 dimensions for virtually all WordPress content libraries.
Query string embeddings and top-k search results are cached in the persistent Redis Object Cache using an MD5 hash of the normalized query string with an active TTL of 24 hours.
Primary references
Aditya Bhimrajka is a technology entrepreneur, product strategist, and software solutions expert with over a decade of experience building scalable web and mobile applications. His expertise spans SaaS, AI, cloud technologies, custom software development, and digital transformation. Passionate about solving real-world business challenges through technology, Aditya shares practical insights on WordPress, plugins, software development, startup growth, product strategy, and emerging technologies. At WPStack, he writes actionable, experience-driven content that helps developers, businesses, and website owners build secure, high-performing, and future-ready WordPress solutions.
Post a Comment